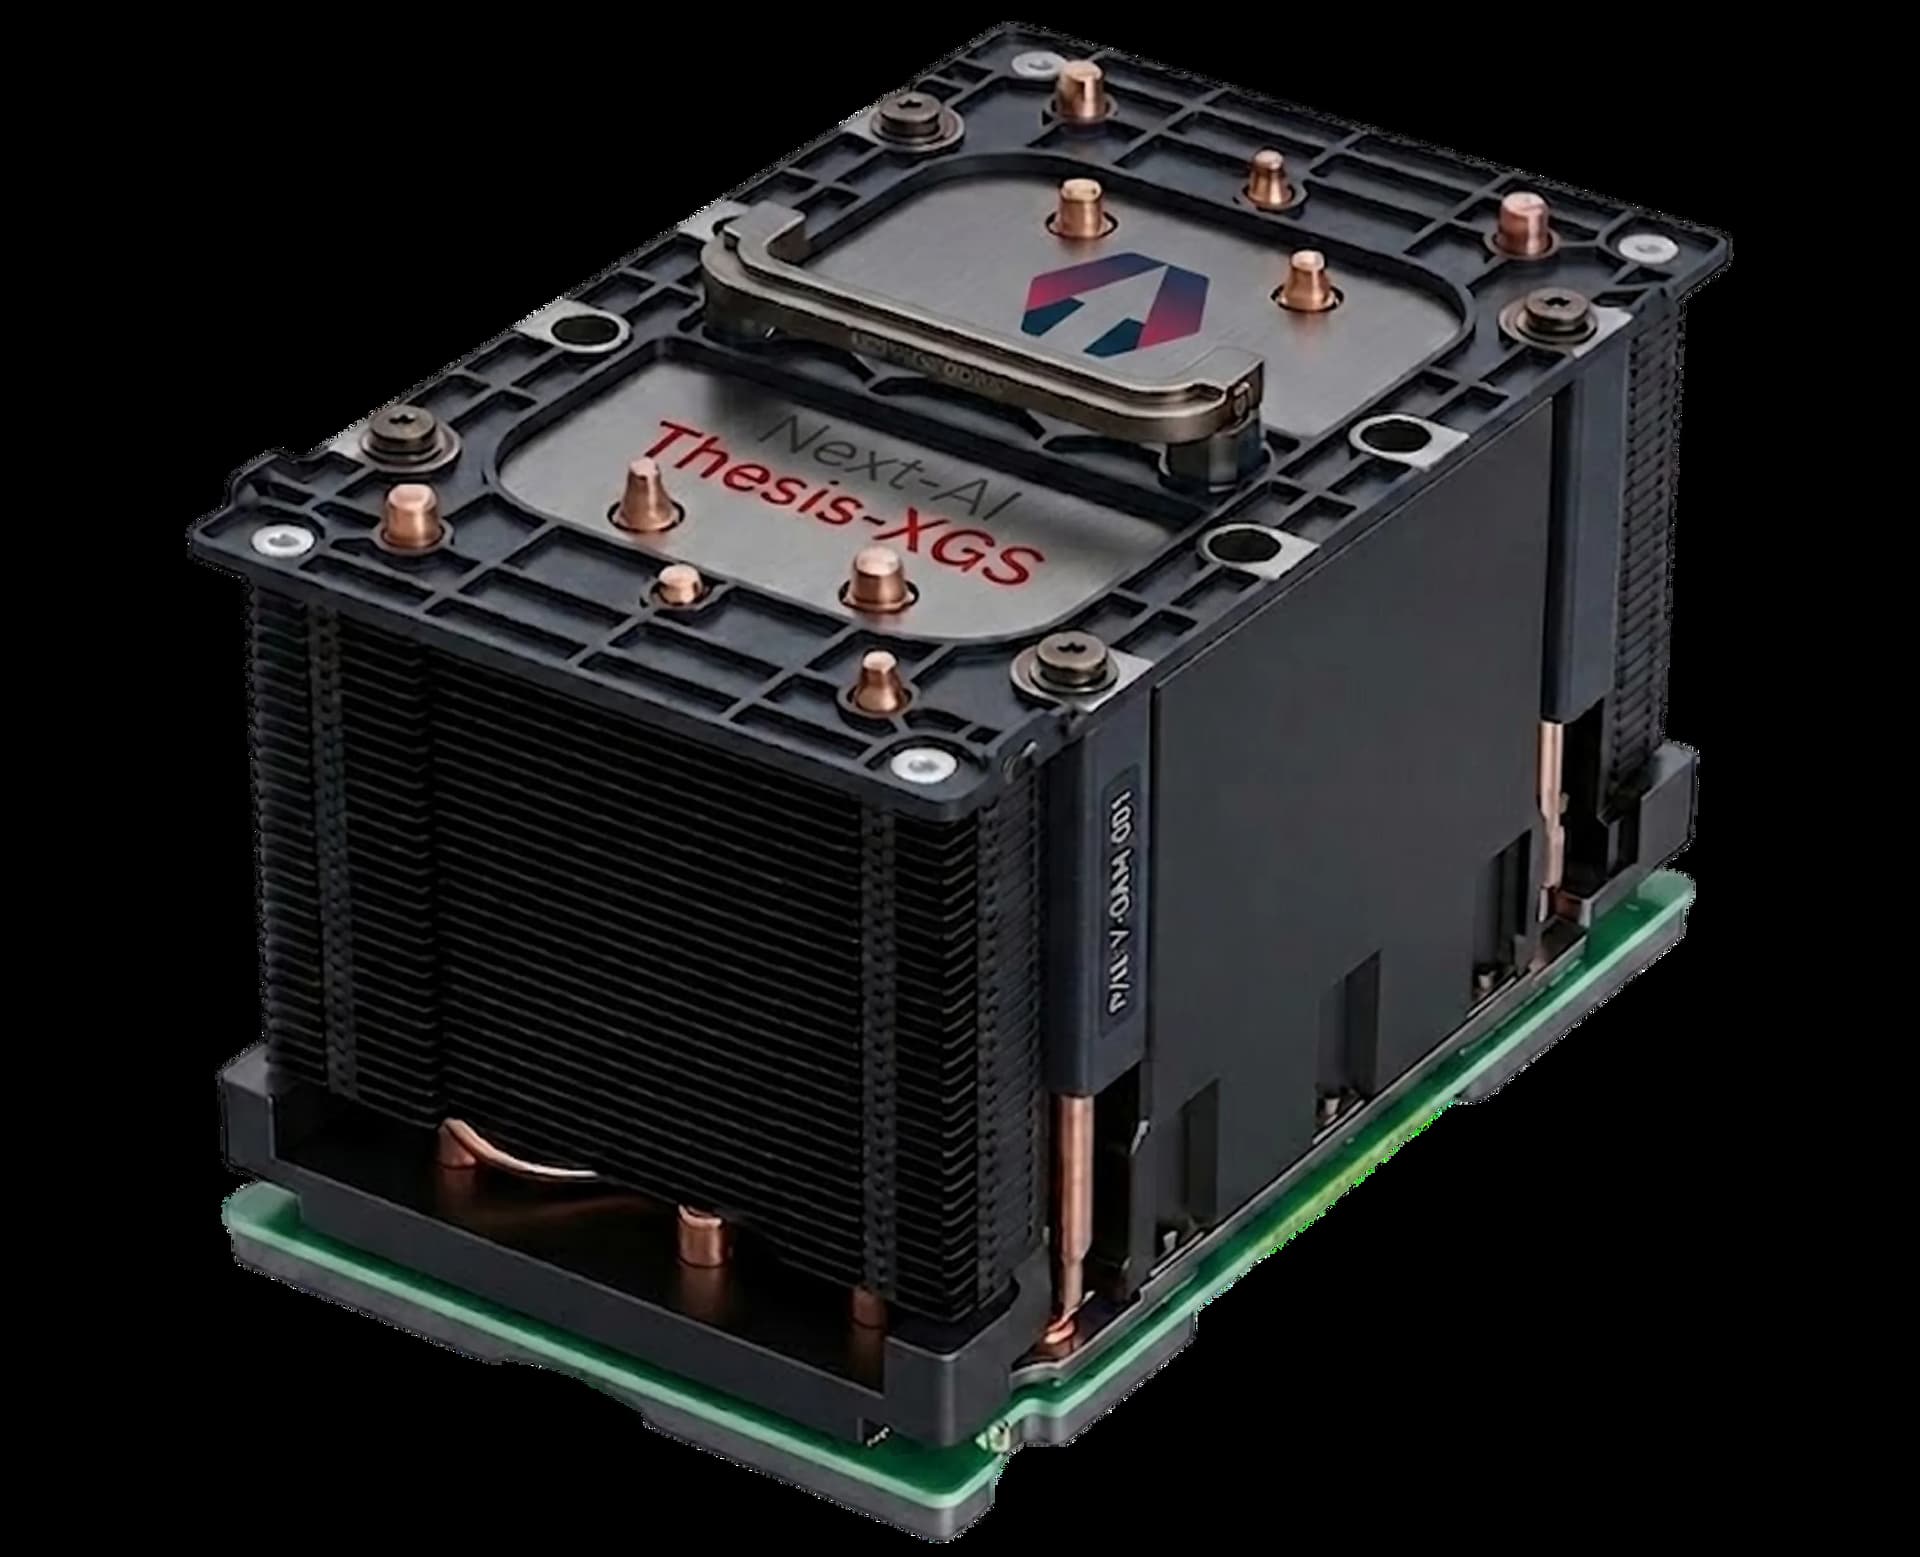
Axiom-X - Enterprise AI Built for Speed, Control, and Efficiency
From copilots and search to real-time decision-making, organizations need predictable latency, cost-effective scale, and the freedom to deploy on their own terms. Axiom-X is built for exactly that.
Why Axiom-X
Modern AI inference infrastructure is shaped by several interacting constraints, not a single bottleneck. Performance depends on the balance between compute, memory bandwidth, and interconnect throughput. When any one of these falls behind, overall efficiency drops, even if the other components are highly capable. As AI workloads scale and become more distributed, maintaining this balance only becomes more critical.
Meeting these challenges calls for a system-level approach to infrastructure design. Rather than optimizing components in isolation, modern architectures focus on coordinating compute resources, memory subsystems, and network fabrics. When these elements are aligned, systems can deliver higher throughput, make better use of resources, and scale AI workloads reliably across diverse environments.
Your AI. Your Data. Your Infrastructure.
Building the future of AI on sovereignty, domesticity, and enterprise strength

Deploy Entirely On-Premises
Inside your data centre, under your governance

Open standards architecture
Leveraging Ultra Ethernet, RISC-V cores, and other open standards to ensure broad ecosystem compatibility and easy integration with existing infrastructure.

Data Sovereignty, Guaranteed
No model weights or traffic ever leave your environment.

Future-Proof by Design
No lock-in to proprietary ecosystems or vendor roadmaps
Inference at Scale, Without Compromise
Inference isn't "one model, one server." It's always-on, multi-step services operating under tight latency and cost constraints. Axiom-X is designed to deliver on the metrics that matter most in production.
Predictable QoS (Consistency at Scale)
Not all inference is equal—SLA matters. Axiom-X is built to deliver stable tail latency and consistent throughput under bursty, multi-user traffic.
Memory-bandwidth optimized (Feeds the model, not the bottleneck)
Built for memory-hungry models, with high bandwidth and efficient data movement to keep pipelines fed and token throughput high.
Ultra scalable
Designed for spiky, multi-tenant services like LLM APIs and recommendation systems—scales from single-node installs to large fleets
Cost efficient
Lowers cost per inference by maximizing useful work and minimizing wasted cycles across real production patterns.
Power efficient
Performance per watt is the new benchmark—power-aware design reduces operating costs and carbon footprint without sacrificing throughput.
Scalable Architecture
Right-sized for every deployment — R&D lab to hyperscale data centre
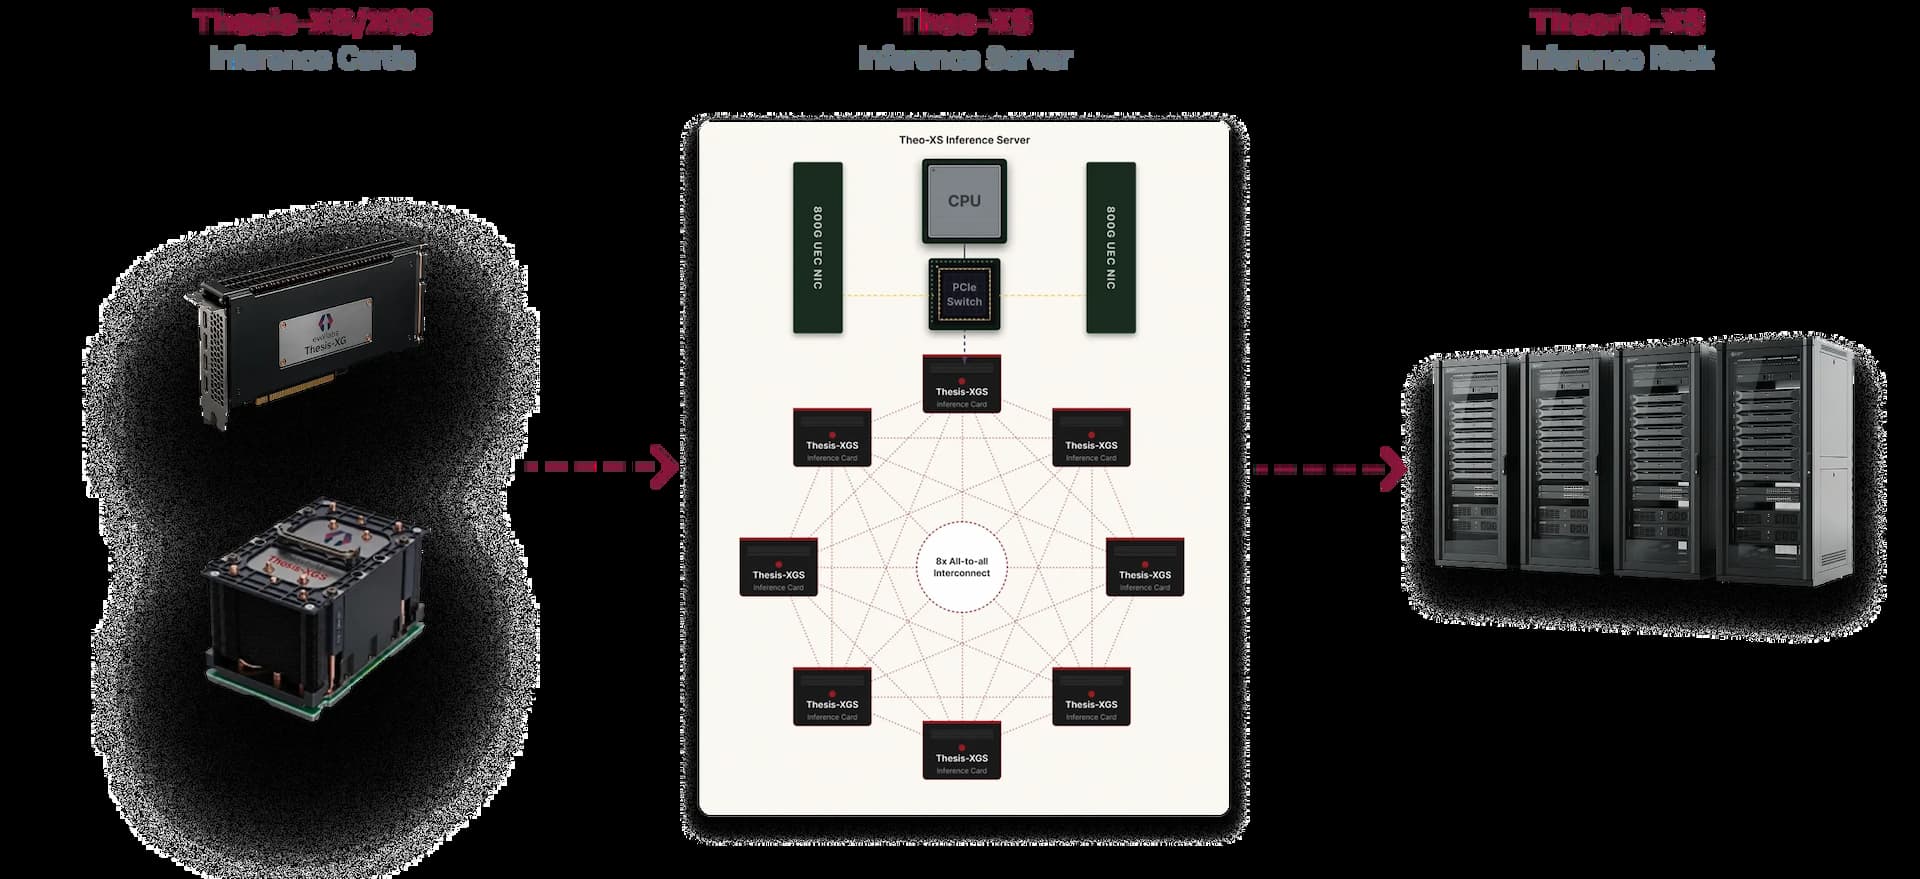
Axiom-XG — Low-Cost Inference Platform
- PCIe cards and servers for AI inference acceleration
- Compatible with third-party servers
- Serving small R&D centres and offline processing
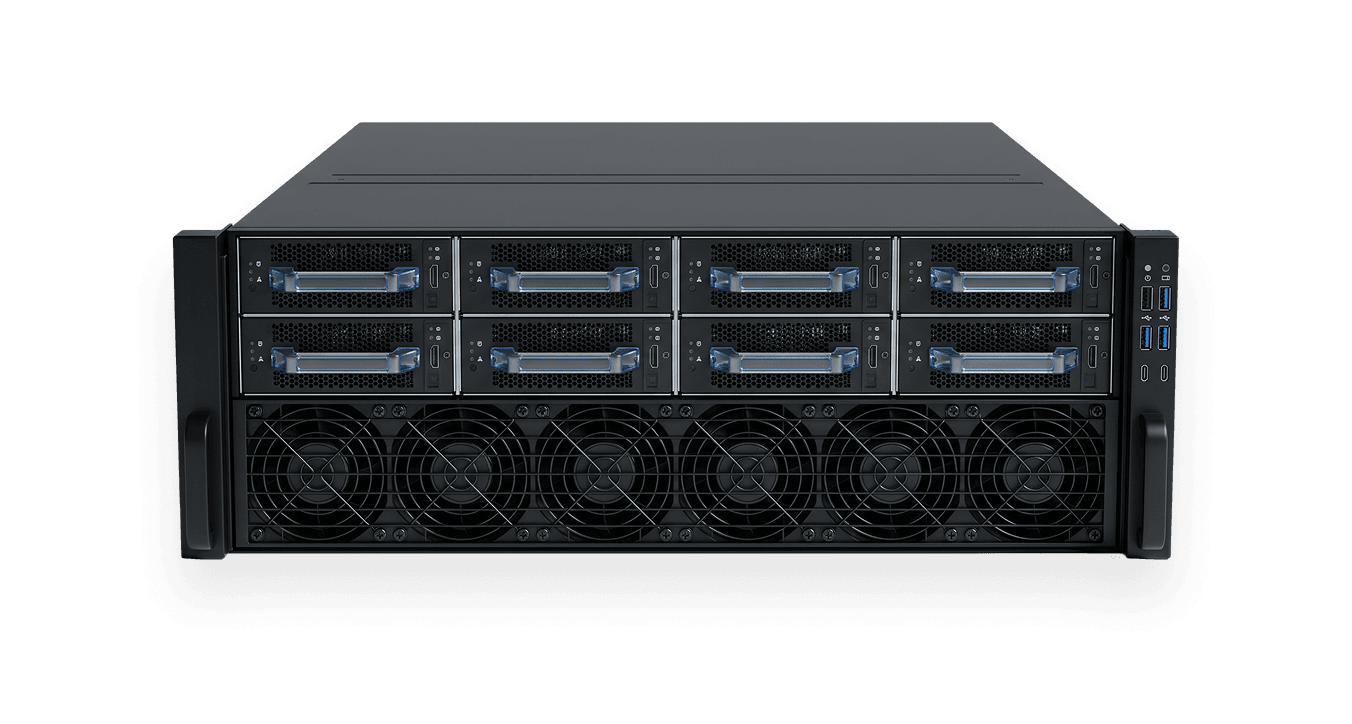
Axiom-XS — Ultra-Fast Inference at Scale
- Disaggregated LLM inference platform
- Accelerators with GDDR memory for attention KV cache management
- Chip with ultra-fast memory for feed-forward layers
- ~10x single-user performance
- ~10× reduction in token price at scale
- Complements existing GPU deployments, extending LLM inference capacity without replacing current infrastructure
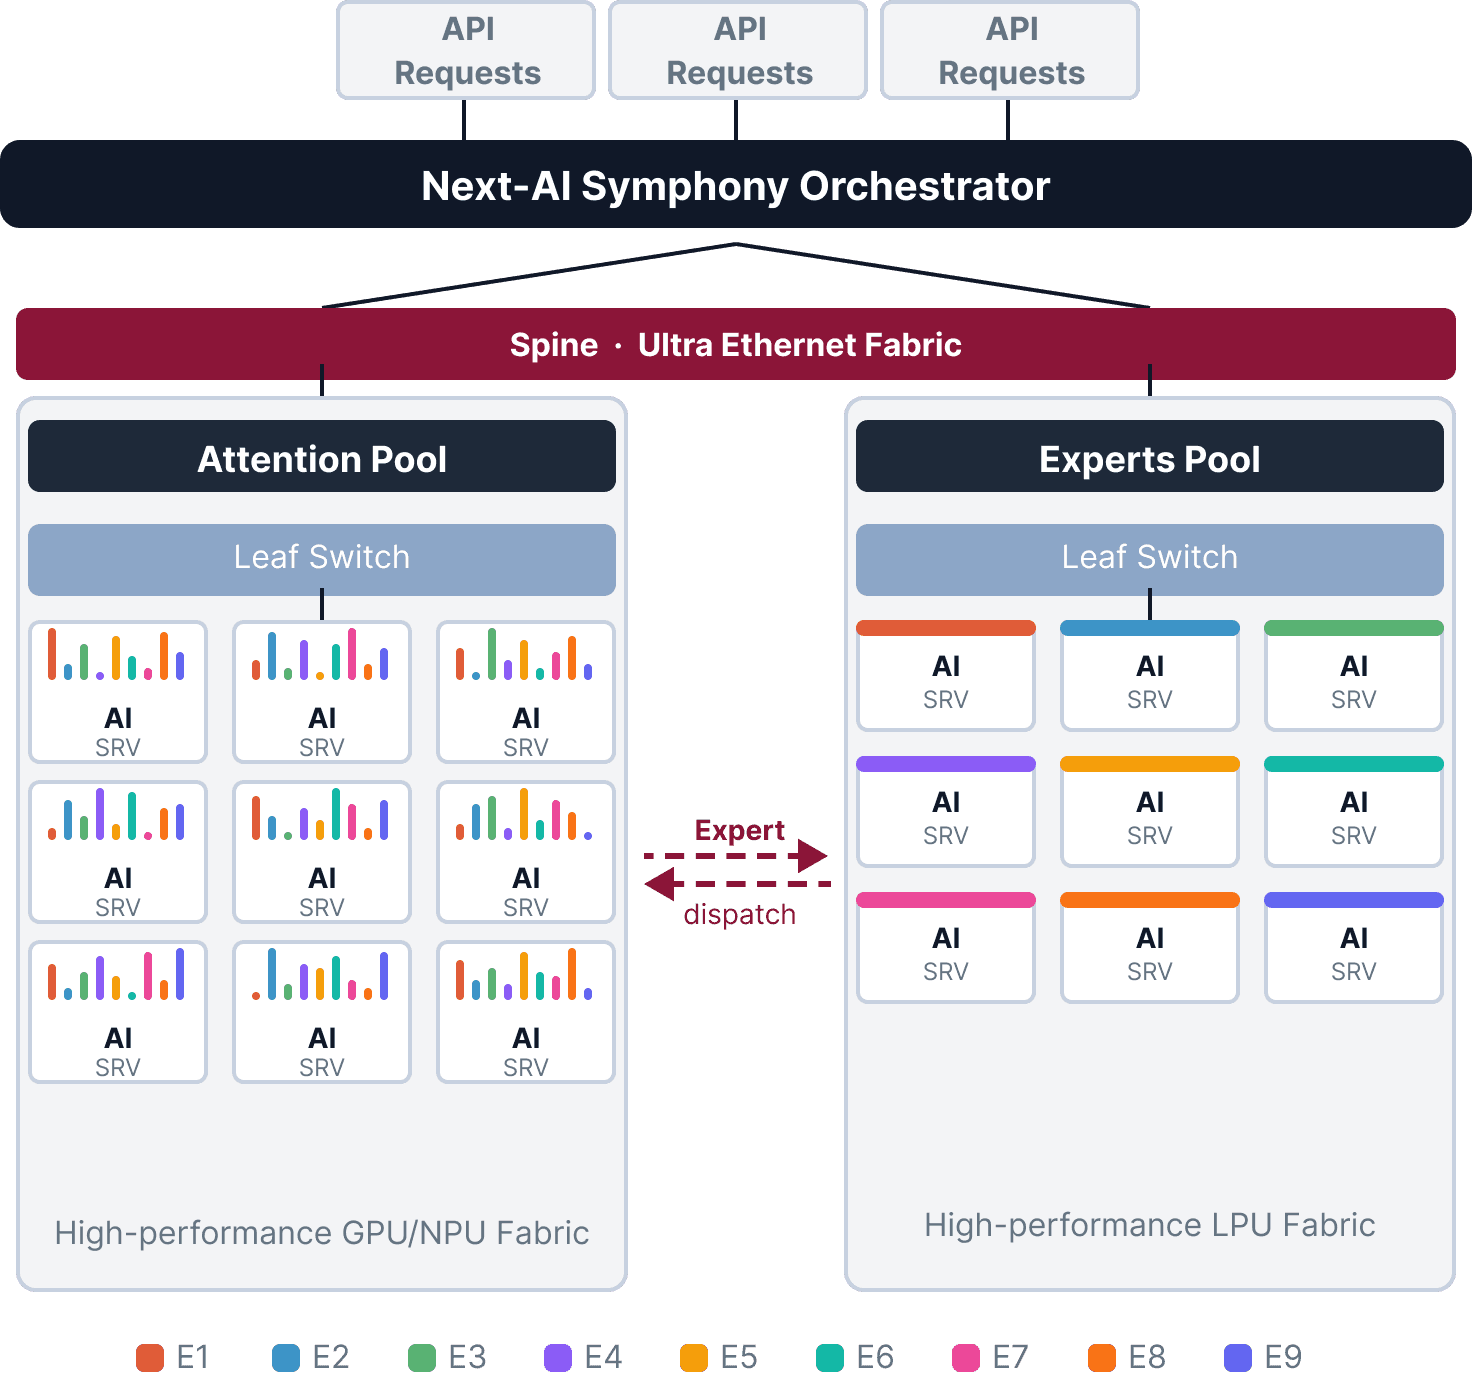
Next-AI Symphony — Orchestration Platform
Full-system orchestration
Manages compute, networking, memory, and routing as one unified system.
OpenAI-compatible API
Drop-in replacement, zero application changes
Disaggregated Serving
Distributes LLM sub-graphs across the right hardware for peak throughput.
Dynamic Load Balancing
Maximises utilisation across heterogeneous nodes
Multi-Vendor Scheduling
Schedule Evollabs and third-party GPUs as one unified cluster.
Built-In Observability
Per-request visibility into latency, throughput, and cost.
KV Cache management
Intelligently routes between GPU and host memory tiers.
Ready to Transform Your AI?
Join the waitlist for early access to Axiom-X and be among the first to experience the next generation of AI computing.
Contact
Evollabs Tech FZ-LLC DIC-Bldg. 05-118, Dubai Internet City United Arab Emirates
© EVOLLABS, all rights reserved.
Developed by SpiderWorks